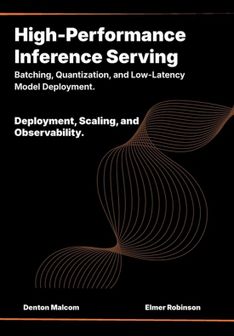
High-Performance Libri GmbH High-Performance Inference Serving Paperback

High-Performance Libri GmbH High-Performance Inference Serving Paperback

Alle 2 prijzen en aanbieders

Hot Deal Alert – Scherpste prijs!
Amazon.be· Bekende aanbieder
€ 37,08
3 tot 4 dagenGratis verzending
Check de website voor de levertijd | Gratis bezorgd > €20,-
Bekijk product
Bekijk product
Amazon.be Marketplace· Marketplace
€ 37,08
3 tot 4 dagenGratis verzending
Check de website voor de levertijd | Gratis bezorgd > €20,-
Bekijk product
Bekijk product

Specificaties

Overige kenmerken
Ondersteuning met updates
Nee
Verpakking breedte
17 cm
Verpakking hoogte
2,1 cm
Verpakking lengte
24,4 cm
Verpakkingsgewicht
635 g
Talen container
en
EAN
9798188217280
EAN
9798188217280
Merk
Libri GmbH

Productomschrijving

Stop burning GPU compute on naive deployments. Transform your models into ultra-low-latency, high-throughput inference engines.

Training a model is only the first step. Serving it in production, handling massive concurrent requests without bankrupting your infrastructure budget or bottlenecking your application is a hardcore systems engineering discipline. Standard Python wrappers and naive API servers collapse under enterprise loads.

High-Performance Inference Serving is the definitive operational manual for architects and MLOps engineers scaling AI in production. We strip away the introductory data science and dive straight into the physics of model serving. You will master the bare-metal realities of the GPU memory wall, KV cache management, and hardware-sympathetic execution required to squeeze maximum throughput from modern accelerators.
>Inside this manual, you will execute:
>State-of-the-Art Compression: Shrinking massive models via PTQ workflows using GPTQ, AWQ, and SmoothQuant to drastically reduce memory bandwidth requirements.

Speculative & Parallel Decoding: Slashing latency with draft models, Medusa, and Lookahead decoding to multiply token generation speed.

Kernel-Level Optimization: Bypassing compiler-generated kernels to implement Operator Fusion and FlashAttention for zero-overhead memory round-trips.

Enterprise Production Architecture: Containerizing inference engines like vLLM, TensorRT-LLM, and Triton, and deploying autoscaling Kubernetes architectures with strict observability SLOs.

Who is this for?
>Stop over-provisioning hardware to compensate for poor architecture. Grab your copy and deploy at scale today.

Er zijn nog geen reviews geschreven

Vraag 1 van 4

Heb jij dit product in bezit en wil je graag je mening geven? Start dan hieronder met het schrijven van je review. Afhankelijk van de details duurt het schrijven van een review gemiddeld tussen de 3 en 10 minuten. Met jouw mening help je andere bezoekers een betere keuze te maken én maak je iedere maand kans op €250,-! Klik hier voor de actievoorwaarden.

Welk cijfer geef jij dit product?