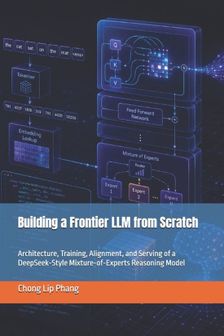
Building Independently Published Building a Frontier LLM from Scratch: Architecture, Training, Alignment, and Serving of a DeepSeek‑Style Mixture‑of‑Experts Reasoning Model Paperback

Building Independently Published Building a Frontier LLM from Scratch: Architecture, Training, Alignment, and Serving of a DeepSeek‑Style Mixture‑of‑Experts Reasoning Model Paperback

Alle 2 prijzen en aanbieders

Meest populaire keuze – Scherpste prijs!
Amazon.be· Bekende aanbieder
€ 18,65
3 tot 4 dagenGratis verzending
Check de website voor de levertijd | Gratis bezorgd > €20,-
Bekijk product
Bekijk product
Amazon.be Marketplace· Marketplace
€ 18,65
3 tot 4 dagenGratis verzending
Check de website voor de levertijd | Gratis bezorgd > €20,-
Bekijk product
Bekijk product

Specificaties

Overige kenmerken
Taal handleiding
en
Product lengte
22,9 cm
Verpakkingsgewicht
463 g
Product breedte
15,2 cm
Verpakking lengte
22,9 cm
Verpakking breedte
15,5 cm
Product hoogte
2,7 cm
Verpakking hoogte
3 cm
EAN
9798182010832

Productomschrijving

Most "build an LLM" books stop at a small GPT. This one takes you all the way to the frontier.Today's leading models - DeepSeek-V3, GLM, and the reasoning systems behind them - are not just bigger GPTs. They are sparse Mixture-of-Experts networks with Multi-head Latent Attention, trained in FP8 across thousands of GPUs and taught to reason with reinforcement learning. This book builds that entire modern stack from first principles, one component at a time.Starting from tensors and automatic differentiation, you'll implement and understand every layer of a contemporary large language model - tokenization, attention, the transformer block, rotary positions, a decoder-only architecture - and then the techniques that define the frontier: fine-grained Mixture-of-Experts, Multi-head Latent Attention, Multi-Token Prediction, and sparse attention. From there it covers what it actually takes to train, align, and serve such a model at scale.What you'll understand and build:
- The full architecture of a modern MoE language model, component by component
- Pretraining at scale - FP8 training, distributed and pipeline parallelism, stability, and the systems that keep a run alive
- Alignment from SFT and RLHF to DPO and GRPO - the reinforcement-learning recipe behind reasoning models
- Inference and serving - KV-cache optimization, paged attention, quantization, continuous batching
- The research frontier - reasoning, agents, multimodality, and extreme efficiency
- Two full case studies dissecting real frontier models: DeepSeek-V3 and GLM
Who it's for: engineers, researchers, and serious students who know some Python and want to understand modern LLMs deeply enough to build one - not just call an API.Every chapter pairs clear explanation with worked examples, illustrative code, and reference tables, and ends with exercises. The result is a single, self-contained path from import torch to a DeepSeek-style Mixture-of-Experts reasoning model.Stop treating large language models as black boxes. Build one.

Er zijn nog geen reviews geschreven

Vraag 1 van 4

Heb jij dit product in bezit en wil je graag je mening geven? Start dan hieronder met het schrijven van je review. Afhankelijk van de details duurt het schrijven van een review gemiddeld tussen de 3 en 10 minuten. Met jouw mening help je andere bezoekers een betere keuze te maken én maak je iedere maand kans op €250,-! Klik hier voor de actievoorwaarden.

Welk cijfer geef jij dit product?