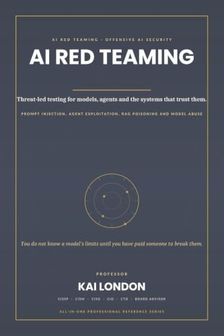
Libri GmbH AI Red Teaming et Sécurité Offensive IA Tout-en-un : Le Manuel Professionnel pour l'Injection de Prompts, l'Exploitation d'Agents, les Attaques LLM, l'Empoisonnement RAG, M

Libri GmbH AI Red Teaming et Sécurité Offensive IA Tout-en-un : Le Manuel Professionnel pour l'Injection de Prompts, l'Exploitation d'Agents, les Attaques LLM, l'Empoisonnement RAG, M

Tous les 2 prix et vendeurs

Choix le plus populaire
Prix le plus bas
Amazon.be· Vendeur reconnu
€ 281,99
3 à 4 joursLivraison gratuite
Check de website voor de levertijd | Gratis bezorgd > €20,-
Voir le produit
Voir le produit
Prix le plus bas
Amazon.be Marketplace· Marketplace
€ 281,99
3 à 4 joursLivraison gratuite
Check de website voor de levertijd | Gratis bezorgd > €20,-
Voir
Voir le produit

Spécifications

Belangrijkste kenmerken
EAN
9798182825351

Description du produit

AI Red Teaming and Offensive AI Security All-in-One is an 805-page professional handbook for prompt injection, agent exploitation, LLM attacks, RAG poisoning, MCP security, model abuse, adversarial testing and AI defence. Organised around the Adversarial Cycle, it treats the testing of AI systems as a board obligation with a defined threat model, governing standards and a repeatable programme, not a one-off stunt.Part I sets out why testing AI systems is now a board obligation, the threat model in terms of positions, goals and techniques, and the standards and authorities that govern the work. Part II covers scoping and discovering the targets: building the AI inventory, finding every model, app and agent and the blind spots of discovery, classifying by exposure, reachability and blast radius, and third parties, SaaS and the AI supply chain. Part III turns to prioritisation, programme design and the business case.Later parts walk through the offensive techniques themselves, from direct and indirect prompt injection, jailbreaks and system-prompt extraction to tool and agent exploitation, retrieval and RAG poisoning, MCP and tool-calling abuse, model theft and abuse, and adversarial machine learning, and then the defences, detection, evidence and governance that turn findings into durable controls.Written for red teamers, penetration testers, AI security engineers, security architects, SOC leaders, CISOs, auditors and governance professionals responsible for AI systems in production. Part of the Understand, Architect, Attack, Defend, Govern series of enterprise AI security references.Key topics include: AI red teaming; prompt injection; jailbreaks; agent exploitation; RAG poisoning; MCP and tool-calling security; model abuse and theft; adversarial machine learning; AI inventory and discovery; AI supply chain; AI security programme design; AI defence and governance.

Aucun avis n’a encore été écrit

Question 1 sur 4

Tu possèdes ce produit et tu aimerais donner ton avis ? Commence ci-dessous à écrire ton avis. Selon le niveau de détail, écrire un avis prend en moyenne entre 3 et 10 minutes. Avec ton opinion, tu aides les autres visiteurs à faire un meilleur choix et tu tentes chaque mois de gagner 250 € ! Clique ici pour les conditions de l’action.

Quelle note donnes-tu à ce produit ?