LLM Libri GmbH Production AI Engineering- LLM Inference Engineering

LLM Libri GmbH Production AI Engineering- LLM Inference Engineering

Tous les 2 prix et vendeurs

Hot Deal Alert – Meilleur prix !
Amazon.be· Vendeur reconnu
€ 9,18
3 à 4 joursLivraison gratuite
Check de website voor de levertijd | Gratis bezorgd > €20,-
Voir le produit
Voir le produit
Amazon.be Marketplace· Marketplace
€ 9,18
3 à 4 joursLivraison gratuite
Check de website voor de levertijd | Gratis bezorgd > €20,-
Voir le produit
Voir le produit

Spécifications

Overige kenmerken
Product breedte
15,2 cm
Product hoogte
0,4 cm
Product lengte
22,9 cm
Taal handleiding
en
Verpakking breedte
15,2 cm
Verpakking hoogte
0,4 cm
Verpakking lengte
22,9 cm
Verpakkingsgewicht
122 g
EAN
9798180985187

Description du produit

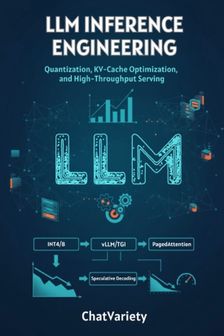
Master the Art of Low-Latency, High-Throughput LLM ServingIn 2026, the defining challenge of production AI is no longer training-it is cost-effective inference. LLM Inference Engineering is the definitive production guide for software engineers, ML developers, and DevOps professionals tasked with deploying large language models at scale without breaking the bank.This hands-on manual strips away the theoretical academic jargon and delivers practical, production-ready strategies to cut your GPU and cloud serving costs by 50% to 70% while maintaining absolute response quality.What You Will Master: - Advanced Quantization: Hands-on implementation of INT4/INT8 quantization using AWQ, GPTQ, and GGUF algorithms without destroying model accuracy.- High-Throughput Architectures: Deep dives into PagedAttention, continuous batching, and GPU memory management to maximize hardware utilization.- Serving Frameworks: Configuration recipes and production tuning guidelines for vLLM, TGI (Text Generation Inference), and llama.cpp.- Speed Optimization: Implement speculative decoding to achieve 2x to 4x latency reduction with mathematically guaranteed quality.- Scaling to 70B+ Models: Configure multi-GPU setups using tensor parallelism to distribute memory footprints efficiently.- Rigorous Benchmarking: Establish robust metrics for latency, cost-per-token, and throughput to justify infrastructure decisions.Written specifically for practicing engineers, this guide assumes familiarity with Python and basic PyTorch. Inside, you will find real-world deployment examples, benchmarking code, and architectural breakdowns that bridge the gap between model training and highly scalable production deployments. Equip yourself with the skills to architect the next generation of AI infrastructure. Stop wasting expensive GPU cycles-optimize your inference pipeline today.

Aucun avis n’a encore été écrit

Question 1 sur 4

Tu possèdes ce produit et tu aimerais donner ton avis ? Commence ci-dessous à écrire ton avis. Selon le niveau de détail, écrire un avis prend en moyenne entre 3 et 10 minutes. Avec ton opinion, tu aides les autres visiteurs à faire un meilleur choix et tu tentes chaque mois de gagner 250 € ! Clique ici pour les conditions de l’action.

Quelle note donnes-tu à ce produit ?